Discovery API: Creator Search From Inside Your Own Stack
Query Favikon's creator index programmatically instead of through a search screen. What it replaces, and the first job worth building.
Creator search is a screen today. For most teams that is the right shape. For a few, it is the bottleneck: the data is needed somewhere else, on a schedule, without a person in the loop.
Discovery API is that route. It is coming to Pro and Enterprise, and this page is what it is for.
What it replaces in your stack today
If you run creator programmes at any volume, one of these is probably happening in your team right now:
- Somebody exports a CSV from a search screen every week and pastes it into a sheet that feeds a dashboard.
- Creator data lives in one tool and campaign performance lives in another, and the join is a person.
- Your own product needs creator data in it, and the current answer is a scrape you do not want to talk about.
Each of those is the same missing piece: a programmatic way to ask the index a question and get a structured answer back.
The one job worth building first
A scheduled sync into your own database.
It sounds unglamorous next to the dashboards people imagine building, and it is the thing that actually changes how a team works. Once creator records live in your warehouse next to your campaign data, the questions that were previously an afternoon of manual joining become a query: which creators drove pipeline, which tiers convert in which markets, what a partnership is worth against its cost.
Everything else people build on a creator API is downstream of having the data somewhere you can join it.
What a response looks like
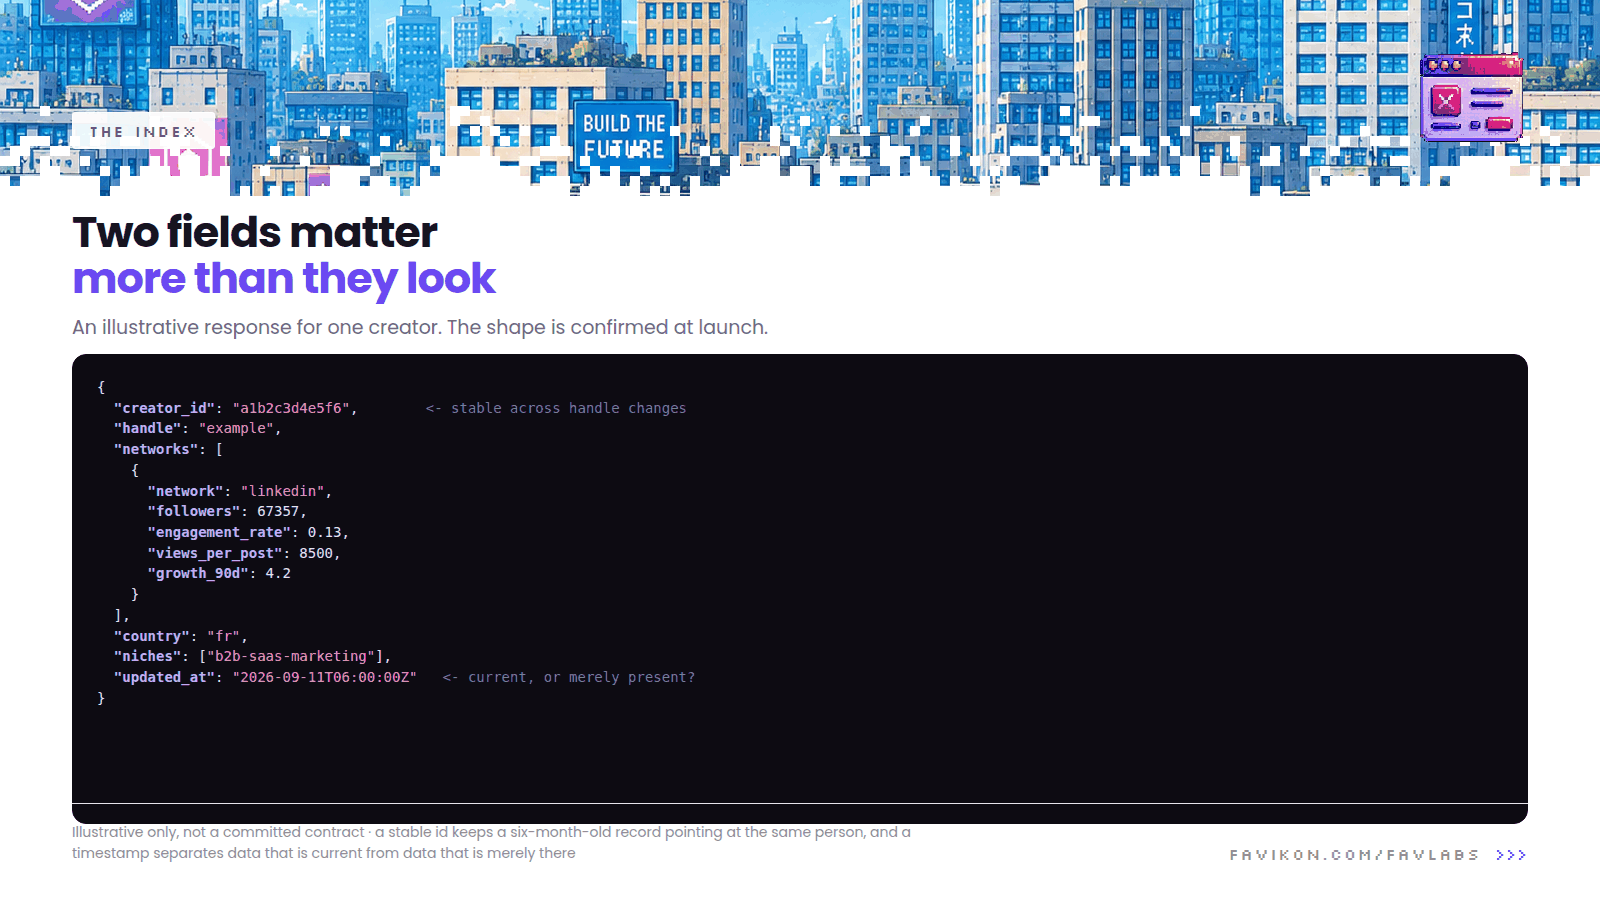
Illustrative only, and not a committed contract. The shape will be confirmed at launch.
{
  "creator_id": "a1b2c3d4e5f6",
  "handle": "example",
  "networks": [
    {
      "network": "linkedin",
      "followers": 67357,
      "engagement_rate": 0.13,
      "views_per_post": 3100,
      "growth_90d": 4.2
    }
  ],
  "country": "fr",
  "niches": ["b2b-saas-marketing"],
  "updated_at": "2026-09-11T06:00:00Z"
}
Two fields matter more than they look. A stable creator ID, so a record you stored six months ago is still the same person today across handle changes. And updated_at, so you can tell the difference between current data and data that is merely present.
Early access
Discovery API is coming to Pro and Enterprise. If you have a specific integration in mind, tell us when you book: the shape of the first release is still being set, and teams with a concrete use case have real influence on it.
In the meantime, the Favikon MCP already exposes the index programmatically to Claude, ChatGPT and any MCP-capable coding agent, on the Free Trial, Pro and Enterprise plans. For a lot of the workflows people want an API for, that is enough today.
Others Tools